Research / tokenizerWorkshop research · measured tokenizer metrics
A smaller vocabulary, fitted to Polish
A from-scratch BPE study measures vocabulary size, token fertility and out-of-domain behaviour on Polish text.
Repository-reported evidence, presented with its original scope. This web edition does not rerun the experiments or change the source’s result status.
How many tokens does a Polish word cost?
Problem
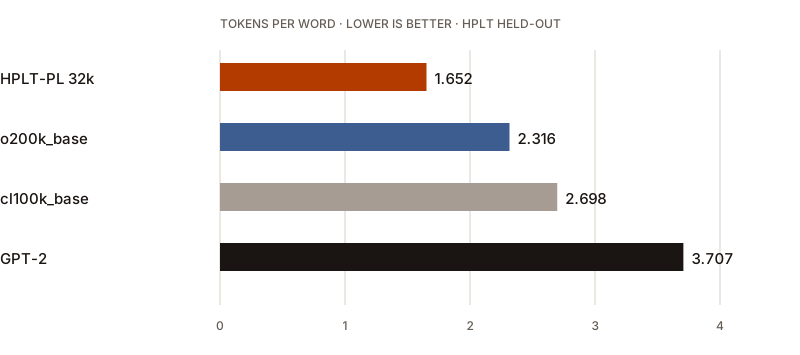
A multilingual vocabulary can be large while using relatively few of its entries on Polish. This study asks how much a Polish-trained byte-level BPE vocabulary changes the token budget, and how the result behaves outside its training domain.
Source note at the inspected revision ↗
Prior art
The comparison uses GPT-2, cl100k_base and o200k_base as reference tokenizers. It also compares Polish-oriented and GPT-2-style pretokenisation within its own implementation. These are tokenizer experiments; model capability and training efficiency are not measured.
Source note at the inspected revision ↗
Baseline & falsification threshold
The primary comparison is fertility on the same held-out text. Lossless encoding is a correctness requirement. The source gives no pre-registered statistical or practical threshold for adopting a tokenizer, so numerical compression improvements remain descriptive rather than a model-selection verdict.
Source note at the inspected revision ↗
Mathematical formulation
Blok kodu, przewijany w poziomiefertility = number of tokens / number of words
round trip: decode(encode(text)) = text
Vocabulary expansion trades shorter sequences for more embedding entries. Its model cost depends on hidden width and whether input/output embeddings are tied; fertility alone cannot determine the best model vocabulary.
Source note at the inspected revision ↗
Method
The implementation uses a complete byte alphabet, explicit merge tie-breaking and pretoken boundaries. A simple reference BPE core and an incremental trainer are checked for parity. The source reports lossless round trips and twelve passing implementation tests.
Source note at the inspected revision ↗
Experiment
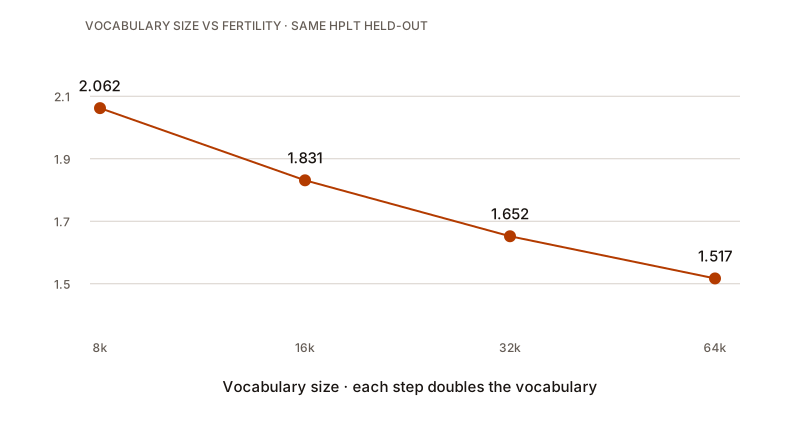
Training uses 314.6 MB from one cleaned Polish HPLT shard. A separate row group supplies the 10.5 MB held-out. The vocabulary sweep covers 8k, 16k, 32k and 64k. Additional evaluations use 3.4 MB of literature and 0.7 MB of Polish Wikipedia.
Source note at the inspected revision ↗
Research
Vocabulary size has a larger measured effect than the tested regex change. At 32k, Polish-oriented pretokenisation gives fertility 1.652 and GPT-2-style pretokenisation 1.647. The small difference does not support the expected advantage of the Polish regex. There is no repeated-run noise estimate establishing a general equivalence claim.
Source note at the inspected revision ↗
Verification
All headline reference tokenizers share the same held-out within this study. The Polish 32k tokenizer retains lower fertility than cl100k_base on literature (1.856 versus 2.591) and Wikipedia (1.885 versus 2.988). These are two modest out-of-domain samples; other contributors’ studies use different corpora and must not be merged into this comparison.
Source note at the inspected revision ↗
Result
The 32k Polish tokenizer achieves 1.652 tokens per word, versus 2.698 for cl100k_base in the HPLT evaluation. Larger vocabularies lower fertility further with diminishing gains. No downstream model accuracy or general language-understanding improvement is established.
Source note at the inspected revision ↗
Provenance
Inspect the original work.
Credit: maciej · tokenizer repository contributor. Editorial web adaptation: Fabryka AI.
Original report and surrounding artifacts ↗
Repository: slayerlabs/tokenizer
Revision: 1b25efca5c1a3891edcfdc47a8945b55e531223c. Repository and source licenses apply; this summary grants no additional rights to the source material.